Current-generation GPUs, engineered as one system.
We design every layer together, from power and cooling to the software platform, so your cluster performs as a whole.
The accelerators your workloads need.
We build on current NVIDIA platforms and offer AMD options, at scales from hundreds to thousands of GPUs.
HGX B300
Blackwell Ultra systems for large-scale training and high-throughput inference.
GB300 NVL72
Rack-scale, liquid-cooled systems for the largest models and reasoning workloads.
Vera Rubin
Next-generation platform, offered as it becomes available.
Instinct options
AMD accelerators where they fit your workload and software stack.
Engineered from the data hall to your workloads.
One integrated design across every layer. TensorCove provides the infrastructure and platform. Your models and data stay yours.
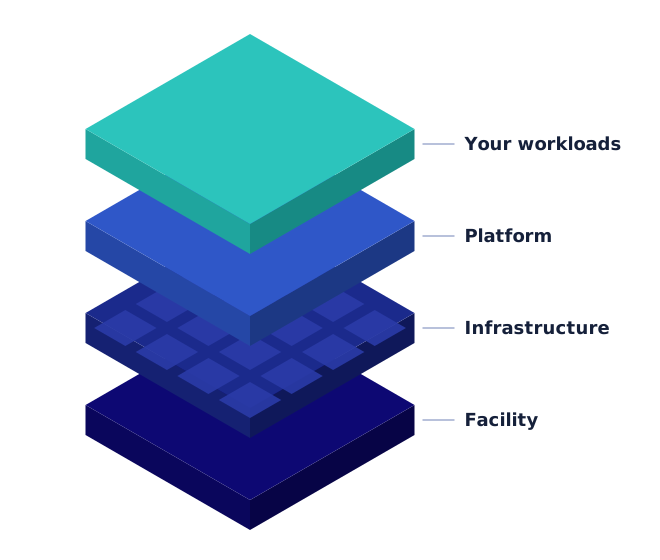
Facility
- Data center and building management (BMS)
- Liquid or air cooling
- Power integration
Infrastructure
- NVIDIA B300, GB300 and Vera Rubin (as available)
- AMD GPU options
- CPU, storage and networking
Platform
- NVIDIA AI Enterprise
- Run:ai
- Kubernetes or Slurm
Your workloads
- Your models or open-source models
- Training and inference environments
- Production AI workloads
On our power or at your site.
TensorCove capacity
Deploy in our planned power capacity. We handle the facility, power and cooling end to end.
Your facility
We design and build the cluster in your data center and integrate with your power, cooling and building systems.
A multi-vendor supply chain, built for schedule certainty.
We source every layer from several qualified vendors, so no single supplier holds up your build.
GPU servers
Dell
Supermicro
Quanta
AI fabric switches
NVIDIA
Arista
Juniper
Optical transceivers
NVIDIA
ATOP
Fiber and cabling
Corning
LINKSIA
Power and racks
Schneider Electric
Lite-On
Rakworx
Ready to plan your cluster?
Tell us about your workload and timeline. We will come back with a cluster design and a proposal.