Operations
24/7 operations, from facility to GPU.
We monitor every level of your cluster around the clock and act on alerts before they affect your workloads.
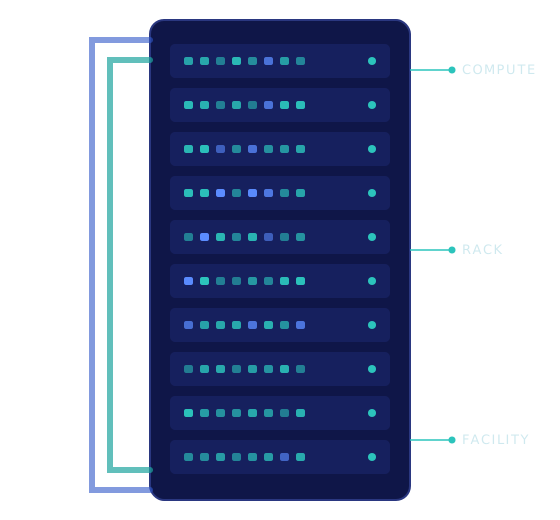
What we monitor
Three levels, one operations team.
Facility
Power, cooling and physical security
Utility feed, cooling plant, leak and temperature alarms, access control.
Rack
Rack power and liquid cooling
Load per power circuit, coolant flow and temperature.
Compute
GPU, node and network health
GPU errors and temperatures, node status, InfiniBand or Ethernet fabric.
Built for uptime
Redundancy, spares and rapid response behind every commitment.
- Redundant network paths
- Redundant (N+1) power and cooling
- Active spare-parts inventory and regional spares
- 24/7 operations team with rapid on-site dispatch
Integrations
Your tools
Stream alerts and metrics into your ticketing and monitoring systems.
Reporting
Clear reporting
Daily, weekly and monthly health and utilization reports.
Lifecycle
Lifecycle support
Defined RMA escalation, advance-replacement agreements and regional spare-part pools.
Ready to plan your cluster?
Tell us about your workload and timeline. We will come back with a cluster design and a proposal.